What TanStack Query taught me about managing server state
Fetching data is easy. Keeping it fresh, synchronized and predictable across a large application is where TanStack Query becomes valuable.
 Alexander Claes
7 min read
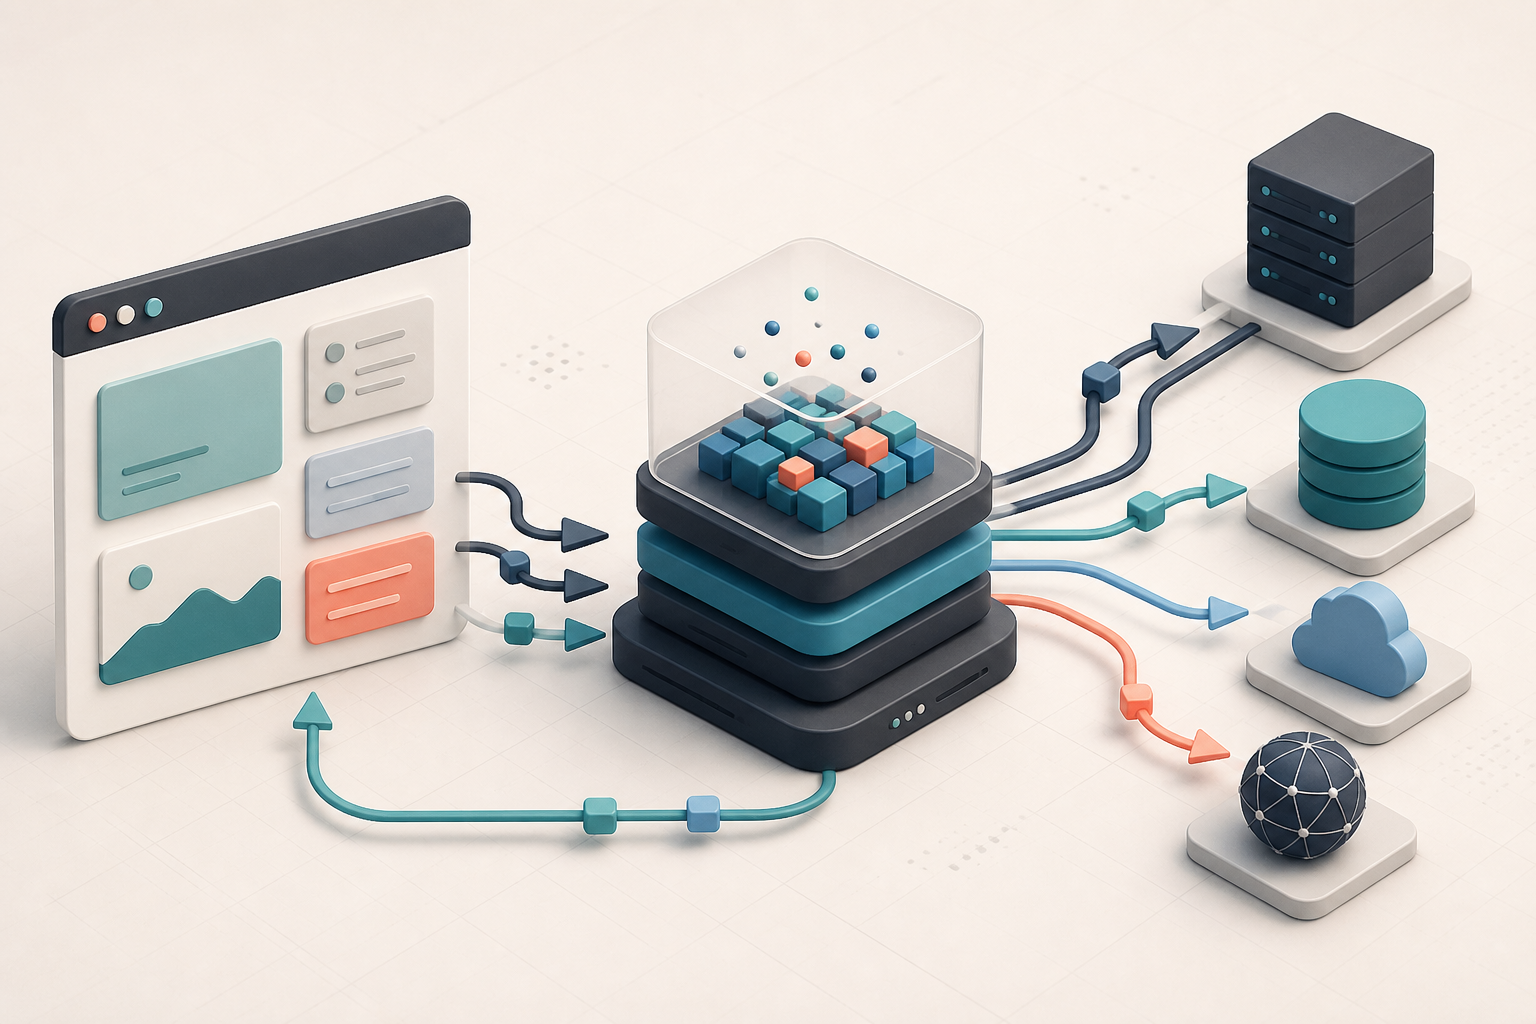
Fetching data from an API is easy. Keeping that data correct across a large application is where things become more complicated.
On the e-Procurement platform at FOD BOSA, the front end has to work with many different kinds of server data. There are dossiers, publications, agreements, purchase requests, purchase orders, approval flows, organisations, users and suppliers. The same data can appear in lists, detail pages, dialogs and related workflows. It can also be changed by another user while you are looking at it.
For this kind of application, fetching data inside a component and storing the result in a local variable quickly stops being enough. You need to think about caching, freshness, retries, loading states, mutations and keeping different parts of the interface synchronized.
TanStack Query has helped us handle a lot of that complexity. The biggest benefit is not that it makes an HTTP request shorter. It gives us a consistent model for working with server state.
Server state is not the same as client state
A useful distinction TanStack Query encourages is the difference between client state and server state.
Whether a dialog is open, which tab is selected or whether a sidebar is collapsed are examples of client state. The front end owns that information.
A purchase request returned by an API is different. The server owns it. It might have changed since we fetched it. Another user might have approved it, an agreement might have been updated or the current user might no longer have permission to perform an action.
Before using a dedicated server-state library, it is tempting to put both kinds of state in the same store. That works, but it means we also have to build our own rules for questions such as:
- When should this data be fetched?
- How long can we reuse it?
- What should happen when the window regains focus?
- Which data is now outdated after a mutation?
- Should a failed request be retried?
- What happens if two components request the same data?
TanStack Query provides a common answer to those questions instead of making every feature solve them independently.
Queries describe data instead of a sequence of steps
A query consists mainly of a key and a function that retrieves the data:
const dossierQuery = useQuery({
  queryKey: ['dossiers', dossierId],
  queryFn: ({ signal }) =>
    api.getDossier(dossierId.value, { signal }),
})
This looks simple, but the returned query contains much more than the eventual response. It represents whether the first request is pending, whether existing data is being refreshed, whether the request failed and whether a retry is paused because the browser is offline.
That makes the component more declarative. It describes the data it needs, while the query handles much of the lifecycle around retrieving it.
It also gives developers throughout the application the same vocabulary. Once you understand how queries work in one feature, a different feature is much easier to follow.
Query keys are part of the architecture
Query keys identify data in the cache. They also determine when queries are shared, refetched or invalidated.
On a small application, creating keys directly inside components might be sufficient. On a large application, a consistent key structure becomes important:
const dossierKeys = {
  all: ['dossiers'] as const,
  lists: () => [...dossierKeys.all, 'list'] as const,
  list: (filters: DossierFilters) =>
    [...dossierKeys.lists(), filters] as const,
  details: () => [...dossierKeys.all, 'detail'] as const,
  detail: (id: string) =>
    [...dossierKeys.details(), id] as const,
}
This hierarchy lets us invalidate exactly what is affected. We can refresh every dossier list, one specific detail page or the entire domain when that is genuinely necessary.
The key also needs to contain every variable on which the request depends. Filters, pagination, sorting, organisation context and identifiers can all change the result. Leaving one of them out can cause the cache to return data for the wrong situation.
That is one of the lessons of using TanStack Query at scale: query keys should not be treated as arbitrary arrays. They form an important part of the application design.
Caching improves more than performance
Caching is often described as a performance feature, but it also improves the experience of navigating through an application.
When users return to a list they recently visited, we can display the existing result immediately and refresh it in the background. When multiple components need the same resource, they can subscribe to the same query instead of maintaining separate copies. Concurrent requests for the same key can also be shared.
The important part is deciding when cached data is still fresh. Not all e-Procurement data has the same freshness requirements. Reference data might remain valid for a long time. The status of a request waiting for approval may need to be checked much more frequently.
TanStack Query provides the mechanism, but it cannot make that decision for us. Choosing an appropriate staleTime still requires understanding the business.
Mutations and invalidation keep screens synchronized
Reading data is only half of the problem. After a user creates, updates or approves something, every affected query needs to reflect the result.
const approveMutation = useMutation({
  mutationFn: approvePurchaseRequest,
  onSuccess: (_, requestId) => {
    queryClient.invalidateQueries({
      queryKey: purchaseRequestKeys.detail(requestId),
    })

    queryClient.invalidateQueries({
      queryKey: purchaseRequestKeys.lists(),
    })
  },
})
Invalidation marks matching data as stale and lets active queries retrieve the authoritative state again. This is particularly useful when the backend applies business rules or returns derived information that would be difficult to reproduce correctly in the browser.
It can be tempting to invalidate everything after every mutation. That is easy and usually correct, but it also creates unnecessary requests. At the other extreme, invalidating too little leaves parts of the interface outdated. A clear query-key structure makes it possible to find a sensible middle ground.
Background refetching creates better loading states
Without a server-state library, loading is often represented by a single boolean. In practice there is an important difference between loading data for the first time and refreshing data that is already visible.
For an initial load, showing a skeleton or loading screen makes sense. During a background refetch, removing the existing content and replacing it with a spinner creates an unnecessary interruption. TanStack Query exposes those situations separately, allowing the interface to keep showing useful information while indicating that it is being refreshed.
That distinction sounds small, but it makes data-heavy applications feel much more stable.
Cancellation helps avoid outdated requests
Users do not always wait for a request to finish. They change filters, open another dossier or navigate away. If every request continues independently, an older response can arrive after a newer one and introduce confusing behaviour.
TanStack Query supplies an AbortSignal to query functions. Passing that signal to our API client allows requests to be cancelled when they are no longer relevant.
Cancellation is easy to overlook when each component implements its own fetching. Making it part of the standard query pattern gives us a more consistent solution.
It is useful, but it is not magic
TanStack Query removes a lot of repetitive infrastructure, but it also introduces concepts that a team needs to understand.
Its defaults can be surprising at first. Cached data is considered stale by default, and stale queries may refetch when a component mounts, the window regains focus or the network reconnects. Those defaults are reasonable, but only when developers know they exist.
Most importantly, TanStack Query is not a replacement for all state management. Form input, temporary UI state and client-only workflows still need an appropriate home. It also does not replace backend authorization or validation. The browser can improve the experience, but the server remains responsible for enforcing the rules.
The main advantage is consistency
The individual features of TanStack Query are useful: caching, background refetching, retries, cancellation, mutations, invalidation and network awareness. On a large project, however, the biggest advantage is that they work together through one consistent model.
Instead of every feature inventing its own approach to fetching and synchronizing data, developers can focus on more relevant questions: What data does this screen need? How fresh should it be? Which queries become outdated after this action? What should the user see while it refreshes?
Those questions still require technical judgment and business knowledge. TanStack Query does not answer them for us, but it gives us much better tools with which to express the answers.